

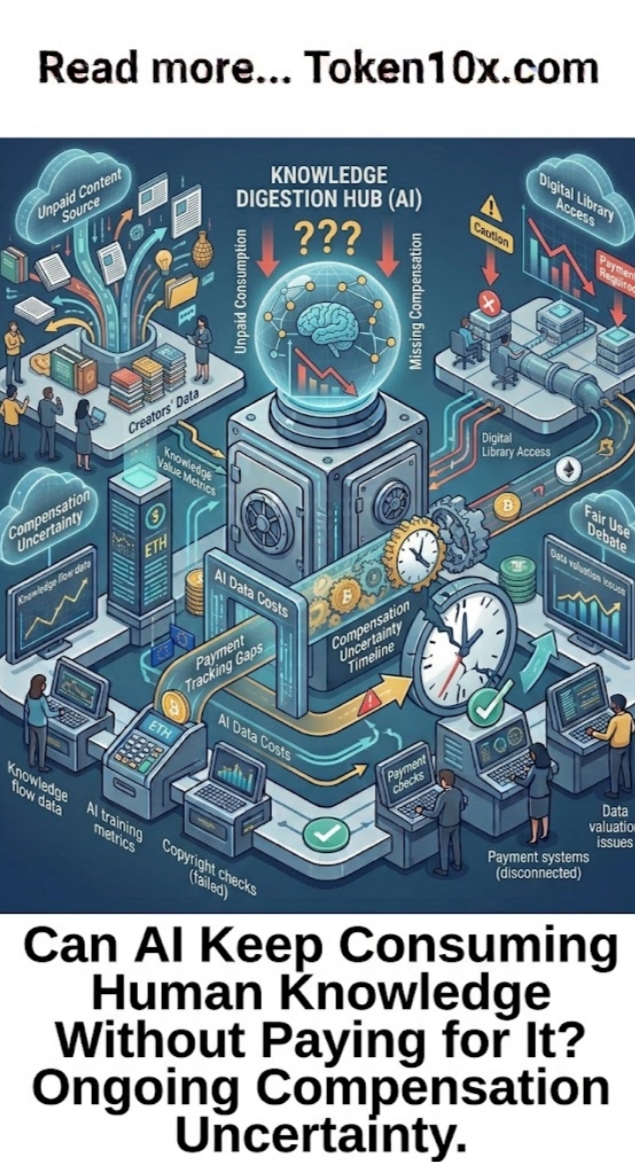
AI systems continue to train on vast quantities of human-created knowledge. As of early October 2026, major models still draw heavily from books, articles, code, art, and online content, much of it scraped or used without direct licenses or payments to original creators. Only a minority of publishers and platforms have secured formal data deals. Uncompensated training remains the dominant practice for many developers.
The industry continues limited voluntary arrangements for some partners. It has restricted certain high-profile datasets in response to lawsuits and opt-out requests. Access to public web data remains available. AI companies rely partly on fair-use arguments and route some training through synthetic or licensed subsets. This highlights the difference between fully licensed, compensated access and the current largely uncompensated model.
The Drivers of the Current Situation
The main issue is the absence of systematic payment mechanisms for the human knowledge that powers AI. Leading developers face ongoing copyright litigation and regulatory scrutiny in multiple jurisdictions. They have stated they will pursue more licensing agreements while defending transformative-use claims. No comprehensive global compensation framework has been adopted yet.
AI firms have limited some data sources. Creators in fields such as journalism, literature, visual arts, and software have seen their work absorbed at scale with little or no revenue share. Some rightsholders still allow access under existing terms. The companies point to fair use, public-benefit arguments, and emerging opt-out tools. Some training has also shifted toward synthetic data or paid partnerships. Courts, lawmakers, and creators’ groups are reviewing whether current practices stay within legal bounds. Only entities with explicit licenses or settled agreements have clear permission to commercialize certain high-value corpora. Most large models are not fully covered by such arrangements.
A fully sustainable model requires routine compensation for human knowledge. Limited access under fair-use claims or selective deals is a narrower path. Regulators and courts are actively examining it. The situation is a structural challenge tied to the scale of modern AI training.
Impact and Broader Context
Questions about AI consuming human knowledge without payment keep growing. Uncompensated use creates uncertainty for creators. It also affects the long-term supply of high-quality training data and the economic viability of knowledge production. National authorities, collective-management organizations, and industry bodies continue to study compulsory licensing, levy systems, and mandatory transparency rules.
The issue drives debate on the ethics and economics of AI development. It raises questions about how strictly copyright and neighboring rights apply to training, the limits of fair use, risks of chilling future creation, effects on creator incomes, and competition between licensed and unlicensed model providers. Stakeholders stress that the current exemption-style practices are narrow and should not permanently bypass payment. AI companies say they are working toward more partnerships and follow applicable laws in the places they operate.
The rapid scaling of generative AI forced the industry into a constrained legitimacy model regarding human knowledge. The current legal and policy review shows how post-training-data rules will apply to frontier systems.
New licensing frameworks, court decisions, or industry standards will clarify whether AI can continue consuming human knowledge without learning how to pay for it.
This analysis uses public court filings, industry reports, creator statements, and company disclosures. Compensation status and data-access practices remain subject to ongoing review and possible enforcement.